BGP Unnumbered
Overview
F5 BIG-IP Next for Kubernetes (BNK) supports BGP Unnumbered for simplified fabric peering. Traditional BGP requires you to assign IP addresses to every peering interface and configure each neighbor by address. BGP Unnumbered removes this requirement by using IPv6 link-local addresses (LLAs) to establish BGP sessions automatically, based on the physical interface rather than a configured IP.
This approach aligns with NVIDIA’s Cloud Partner reference architecture, where spine, leaf, and Top-of-Rack (ToR) switches are interconnected exclusively through Layer 3 BGP Unnumbered direct links. By adopting the same model, BIG-IP Next for Kubernetes compute nodes integrate directly into the fabric without additional IP address management overhead.
This document explains:
What BGP Unnumbered is and why it simplifies fabric configuration.
How neighbor discovery works without hardware support.
What changes in Traffic Management Microkernel (TMM), tmrouted, and OcNOS to enable this feature.
What BGP Unnumbered is
In a traditional BGP deployment, every peering interface needs a configured IP address. You must assign addresses on both sides of each link and reference those addresses in your BGP neighbor configuration. In large data center fabrics with hundreds of links, this creates significant configuration overhead and increases the chance of errors.
BGP Unnumbered solves this problem by using IPv6 link-local addresses instead of assigned IP addresses. Every IPv6-enabled interface automatically generates a link-local address (in the fe80::/10 range) without any manual configuration. BGP Unnumbered leverages these addresses to:
Discover neighbors using IPv6 Router Advertisements (RAs).
Establish TCP sessions using the discovered link-local addresses.
Exchange routes (both IPv4 and IPv6) over those sessions.
Because link-local addresses are auto-generated, you don’t need to plan, assign, or manage IP addresses on peering interfaces. You identify neighbors by interface name instead of IP address.
Traditional BGP vs. BGP Unnumbered
Aspect |
Traditional BGP |
BGP Unnumbered |
|---|---|---|
Neighbor identification |
IP address |
Interface name |
Address assignment |
Required on every peering interface |
Not required (uses auto-generated IPv6 link-local) |
Neighbor discovery |
Manual configuration |
Automatic via IPv6 Router Advertisements |
Configuration per link |
Unique IP pair per link |
Interface name only |
Scaling in large fabrics |
Significant address management overhead |
Minimal — no IP planning required |
Route types supported |
IPv4 and IPv6 |
IPv4 only (current limitation) |
Why BGP Unnumbered is used
NVIDIA Cloud Partner requirements
NVIDIA’s Cloud Partner reference architecture uses BGP as the routing protocol for both the underlay and the Ethernet VPN (EVPN) Virtual Extensible LAN (VXLAN) overlay. The architecture interconnects spine, leaf, and ToR switches exclusively through Layer 3 BGP Unnumbered direct links. This simplifies switch configuration across the entire fabric.
For BIG-IP Next for Kubernetes compute nodes to participate in this fabric, they must support BGP Unnumbered for establishing neighborship with the adjacent leaf or ToR switch.
Key benefits
Simplified configuration: You identify neighbors by interface name instead of IP address. No IP address planning or assignment is needed on peering interfaces.
Reduced operational errors: Fewer configuration parameters mean fewer opportunities for misconfiguration.
Fabric alignment: BIG-IP Next for Kubernetes compute nodes use the same peering model as the rest of the NVIDIA fabric, which simplifies integration and troubleshooting.
How neighbor discovery works
OcNOS normally uses hardware support for BGP Unnumbered neighbor discovery. This hardware support is not available in a Kubernetes environment. To bridge this gap, TMM and tmrouted are enhanced to provide the neighbor discovery function that OcNOS expects.
Discovery flow
The neighbor discovery process involves four components working together:
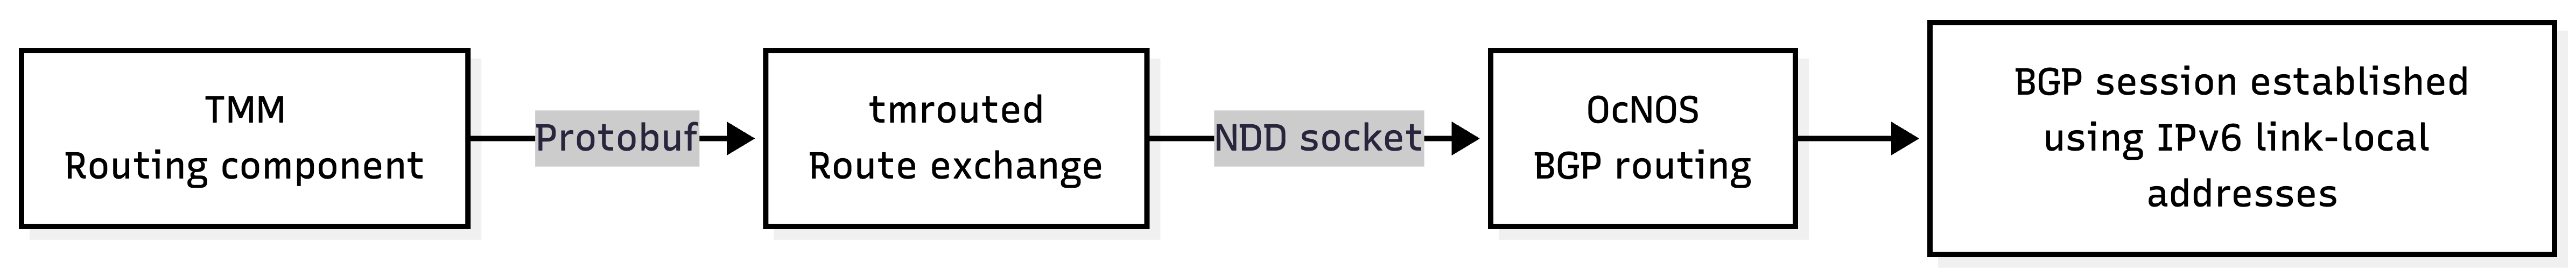
Step-by-step:
TMM sends Router Advertisements When a VLAN without self IPs is identified as a BGP Unnumbered interface, TMM sends periodic RAs on that interface. The RA contains the TMM interface’s link-local address. The RA interval is set to a minimum of 10 seconds and a maximum of 60 seconds.
TMM receives remote RAs When the remote peer (such as a leaf switch) sends its own RA, TMM receives it on the same interface and extracts the peer’s link-local address.
TMM forwards RA data to tmrouted TMM pushes the remote RA data to tmrouted through a protobuf message. When the neighbor state changes to
NEXTHOP_REACHABLE, TMM sends an ADD message. When it changes toNEXTHOP_DELETED, TMM sends a DELETE message.Tmrouted stores and forwards to OcNOS Tmrouted runs a Neighbor Discovery Daemon (NDD) server socket that accepts client connections from OcNOS. When OcNOS connects and registers for IPv6 neighbor updates, tmrouted pushes all stored RA data to the OcNOS client. Any new RA data received after registration is forwarded immediately.
OcNOS establishes the BGP session With the remote peer’s link-local address known, OcNOS establishes a TCP session to the peer on BGP port 179 using IPv6 link-local addresses. The BGP session is established, and route exchange begins.
What happens during the RA exchange
The following is a simplified view of the packet exchange during neighbor discovery and BGP session establishment:
RA exchange (neighbor discovery):
TMM sends an RA to the all-nodes multicast address (
ff02::1) containing its link-local address.The remote peer sends its own RA to
ff02::1containing its link-local address.Both sides now know each other’s link-local addresses.
TCP session (BGP establishment):
TMM (via OcNOS) initiates a TCP connection from its link-local address to the peer’s link-local address on port 179.
The standard BGP OPEN, KEEPALIVE, and UPDATE message exchange follows.
Controller and TMM configuration
Enabling BGP Unnumbered
You can enable unnumbered VLAN support for BGP by updating your deployment configuration. The steps depend on whether you deployed using FLO or Helm.
Enable unnumbered VLAN with FLO
Open the CNEInstance configuration file.
Add the
ENABLE_UNNUMBERED_VLANenvironment variable underspec.advanced.cneController.env:spec: advanced: cneController: env: - name: ENABLE_UNNUMBERED_VLAN value: "true"
Save the file and apply the updated configuration.
Enable unnumbered VLAN with Helm
Open the
values.yamlfile for your Helm deployment.Set
unnumberedBgpEnabledto true andplatformTypeto “other” under the global section:global: platformType: "other" unnumberedBgpEnabled: true
3.Apply the updated values by upgrading the Helm release:
shell helm upgrade <release-name> <chart> -f values.yaml
When this variable is set, the controller treats VLANs without self IPs as BGP Unnumbered interfaces and configures TMM to send RA data on those interfaces.
How the controller identifies unnumbered interfaces
The controller uses a simple rule–any VLAN without self IPs is treated as a BGP Unnumbered interface. When the controller detects a VLAN CR that has no selfip_v4s or selfip_v6s fields, it:
Configures the VLAN on all TMM pods.
Sends a protobuf message to TMM to enable RA configuration on that interface.
TMM begins sending periodic RAs and listening for remote RAs on the interface.
How BGP Unnumbered differs in CRDs
In the GlobalRoutingConfig and RoutingConfig CRDs, BGP Unnumbered neighbors use the interface field instead of the ip field. These fields are mutually exclusive — each neighbor must use one or the other.
Neighbor type |
Field |
Example |
|---|---|---|
Traditional (IP-based) |
|
|
Unnumbered (interface-based) |
|
|
In the RoutingTemplate, the template uses or $nbr.ip $nbr.interface to handle both neighbor types. For BGP Unnumbered, the template includes additional blocks to configure unnumbered mode and activate the neighbor under the correct address family.
How routes are exchanged
Although BGP Unnumbered uses IPv6 link-local addresses for session establishment, the routes advertised over the session can be IPv4. This works through a mechanism called IPv4 routes with IPv6 next-hop. The flow:
OcNOS establishes the BGP session using IPv6 link-local addresses.
OcNOS advertises IPv4 routes with the IPv6 link-local address as the next-hop.
TMM receives these routes and must resolve the IPv6 next-hop to forward IPv4 traffic correctly.
TMM has been updated to handle IPv4 destinations with IPv6 next-hops, which is necessary for the egress use case where dynamic routes from OcNOS use the link-local address of the remote router as the next-hop.
RA data lifecycle
TMM manages RA data based on neighbor state changes:
Neighbor state |
TMM action |
Tmrouted action |
|---|---|---|
|
Sends an ADD protobuf message to tmrouted |
Stores the RA data and forwards it to any connected OcNOS clients |
|
Sends a DELETE protobuf message to tmrouted |
Removes the RA data from its store and notifies connected OcNOS clients |
If the tmrouted-to-OcNOS connection is reestablished (for example, after a restart), OcNOS re-registers for neighbor updates and tmrouted sends a bulk sync of all stored RA data.
OcNOS configuration for BGP Unnumbered
The following OcNOS configuration blocks are relevant to BGP Unnumbered. These are rendered by the RoutingTemplate and applied automatically — you don’t configure OcNOS directly.
Unnumbered mode
router bgp <ASN>
  bgp unnumbered-mode
  neighbor <interface> remote-as external
  exit-unnumbered-mode
This block tells OcNOS to establish a BGP session with the peer on the specified interface using IPv6 link-local addresses. The remote-as external setting indicates an eBGP session where the peer’s ASN is discovered dynamically.
IPv4 unicast activation
  address-family ipv4 unicast
  bgp v4-unnumbered-mode
  neighbor <interface> activate
  exit-v4-unnumbered-mode
  exit-address-family
This block activates the unnumbered neighbor under the IPv4 unicast address family, which allows IPv4 routes to be exchanged over the IPv6 link-local BGP session.
Bidirectional Forwarding Detection (BFD)
  interface <interface>
  bfd interval 100 minrx 100 multiplier 3
  exit
BFD can be configured on the unnumbered interface for fast failure detection. The oamd daemon manages BFD sessions, while the TMM BFD Proxy handles BFD packets.
RoutingTemplate for BGP Unnumbered
The following RoutingTemplate example includes BGP Unnumbered configuration blocks. The template handles both traditional (IP-based) and unnumbered (interface-based) neighbors using the or $nbr.ip $nbr.interface pattern:
apiVersion: k8s.f5net.com/v1alpha1
kind: RoutingTemplate
metadata:
  name: demo-temp
spec:
  body: |
    nvo vxlan enable
    nvo vxlan irb

    nvo vxlan vtep-ip-global 100.100.100.200

    router bgp {{ .global.spec.bgp.startASN }}

    {{- if .global.spec.bgp.neighbors }}
    {{- range $nbr := .global.spec.bgp.neighbors }}
    {{- $peerId := (or $nbr.ip $nbr.interface) }}
    neighbor {{ $peerId }} remote-as {{ $nbr.remoteAs }}

    {{- if $nbr.families }}
    {{- range $fam := $nbr.families }}
    address-family {{ $fam }}
    neighbor {{ $peerId }} activate
    exit-address-family
    {{- if eq $fam "unnumbered-v4" }}
    bgp unnumbered-mode
    neighbor {{ $peerId }} remote-as external
    exit-unnumbered-mode
    address-family ipv4 unicast
    bgp v4-unnumbered-mode
    neighbor {{ $peerId }} activate
    exit-v4-unnumbered-mode
    exit-address-family
    {{- end }}
    {{- end }}
    {{- end }}
    {{- end }}
    {{- end }}

    exit
By referencing the same RoutingTemplate across global and tenant configurations, you ensure consistent BGP and EVPN setup across your environment while still allowing for tenant-specific customization.