F5 XC EMEA Workshop > Class 6 - F5 AI Security > F5 AI Guardrails Source |
Inline implementation
The first implementation method we are going to explore is inline.
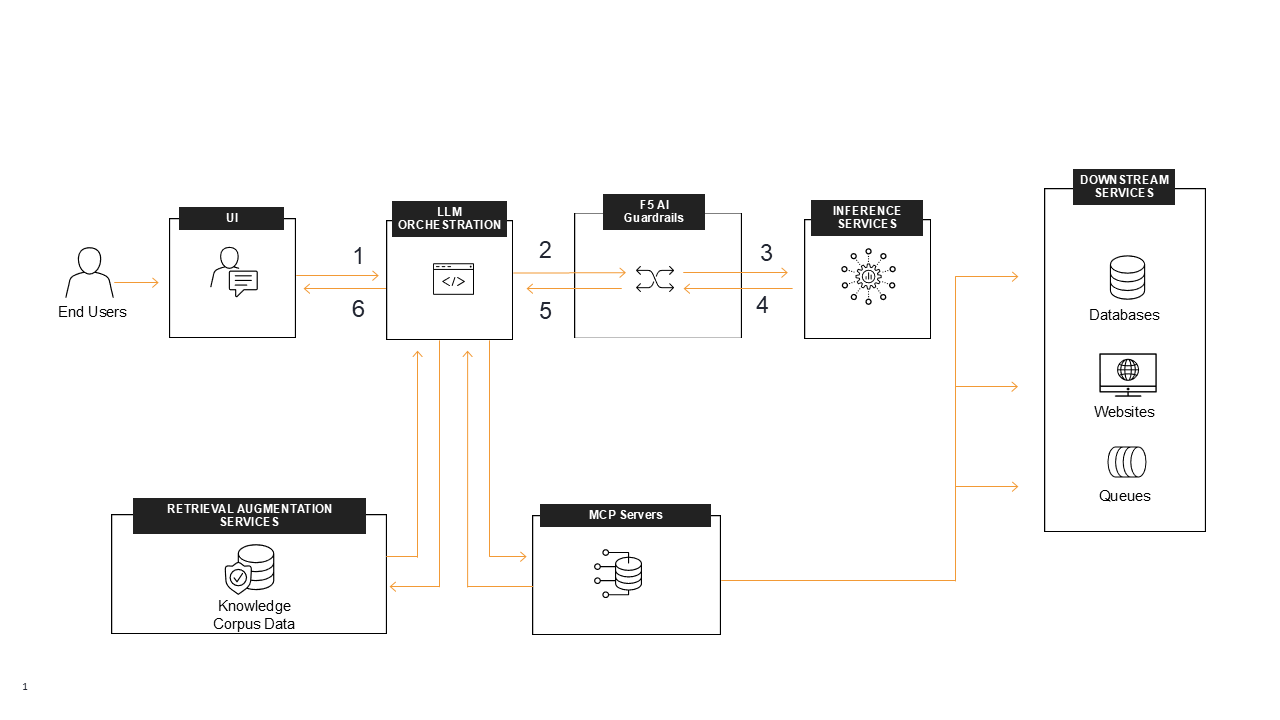
F5 AI Guardrails sits in the inference path and enforces policies in real time, forwarding only clean prompts/responses.
The HTTPS connection will be terminated by F5 AI Guardrails and recreated toward the backend inference endpoint.
The traffic reaching the F5 AI Guardrails endpoint needs to conform to one of the following specs:
- The F5 AI Guardrails API spec detailed here https://docs.calypsoai.com/operations/post_prompts.html or by using the F5 AI Guardrails Python SDK https://docs.calypsoai.com/api-docs/sending-prompt-specific-provider.html
- OpenAI chat completions spec, more info can be found here https://docs.calypsoai.com/api-docs/openai-compatibility.html
Once the request is received, F5 AI Guardrails can transform the request to any inference spec from OpenAI, Ollama, Hugging Face, and more.
Traffic Flow
- The user sends a prompt to the orchestrator.
- The orchestrator builds the full context and sends the API call to F5 AI Guardrails.
- F5 AI Guardrails scans the prompt and, if all is good, forwards it to the LLM inference endpoint. The request will also be transformed when forwarded to the configured inference spec.
- The LLM responds and sends the response to F5 AI Guardrails.
- F5 AI Guardrails scans the response and, if all is good, forwards it to the orchestrator. The response will be transformed to the client-side API spec.
- The orchestrator replies to the user.